Mind the Buffer: Dissecting the LSM-Buffer Design Space
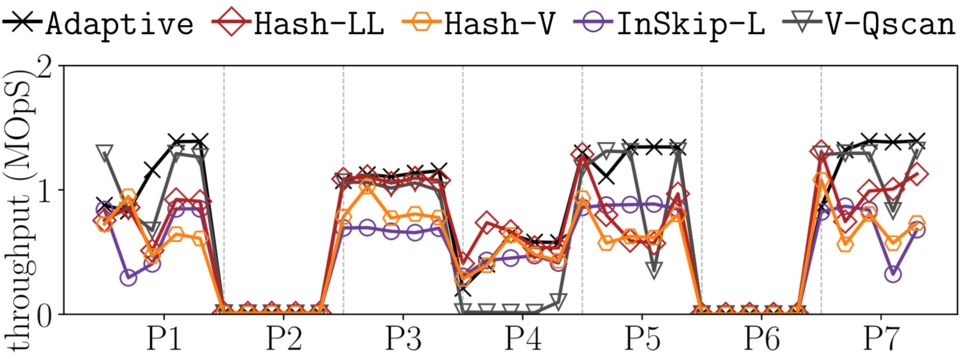
Log-structured merge (LSM)-trees are widely used as the storage layer data structure in modern NoSQL key-value stores due to their superior ingestion throughput, competitive query performance, and efficient space utilization. To enable fast ingestion, LSM-based storage engines first batch the incoming data in an in-memory buffer and then, opportunistically write the data to slower secondary storage as a collection of immutable sorted runs. We point out that while the data is largely storage-resident, the overall performance of an LSM-based storage engine is critically bottlenecked by the (i) implementation, (ii) tuning, and (iii) size of the in-memory buffer. In fact, even with the same buffer configuration, the performance of an LSM-engine may vary by several orders of magnitude if there is a shift in workload. Choosing the appropriate buffer design, thus, is crucial for performance, but, at the same time, hard, as the LSM-buffer design space is vast and largely unexplored. In this paper, we evaluate and analyze the performance of LSM-engines with nine different buffer implementations – including three hash-hybrid designs – while varying the tuning and size for each implementation to understand their implications on performance and the tradeoffs associated. For each configuration, we further vary the workload composition and distribution, the LSM-tuning, and the underlying hardware to quantify their impact on performance. To the best of our knowledge, this is the first comprehensive analysis of LSM-buffer design space. Finally, for the practitioners, we present a handbook with 10 key guidelines for choosing the appropriate buffer design and tuning for a given workload and performance target.
@article{chen2026lsmbufferdesign,
  title = {{Mind the Buffer: Dissecting the LSM-Buffer Design Space}},
  author = {Chen, Boao and Kaushik, Shubham and Sarkar, Subhadeep},
  journal = {53rd International Conference on Very Large Data Bases},
  year = {2027}
}